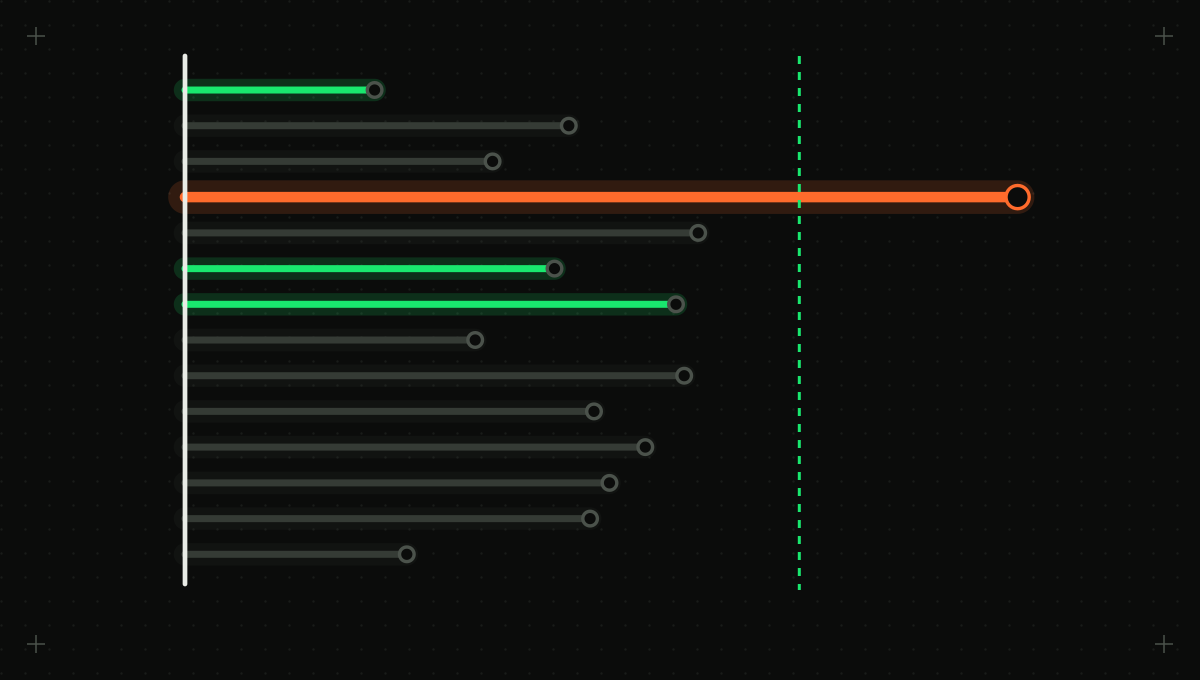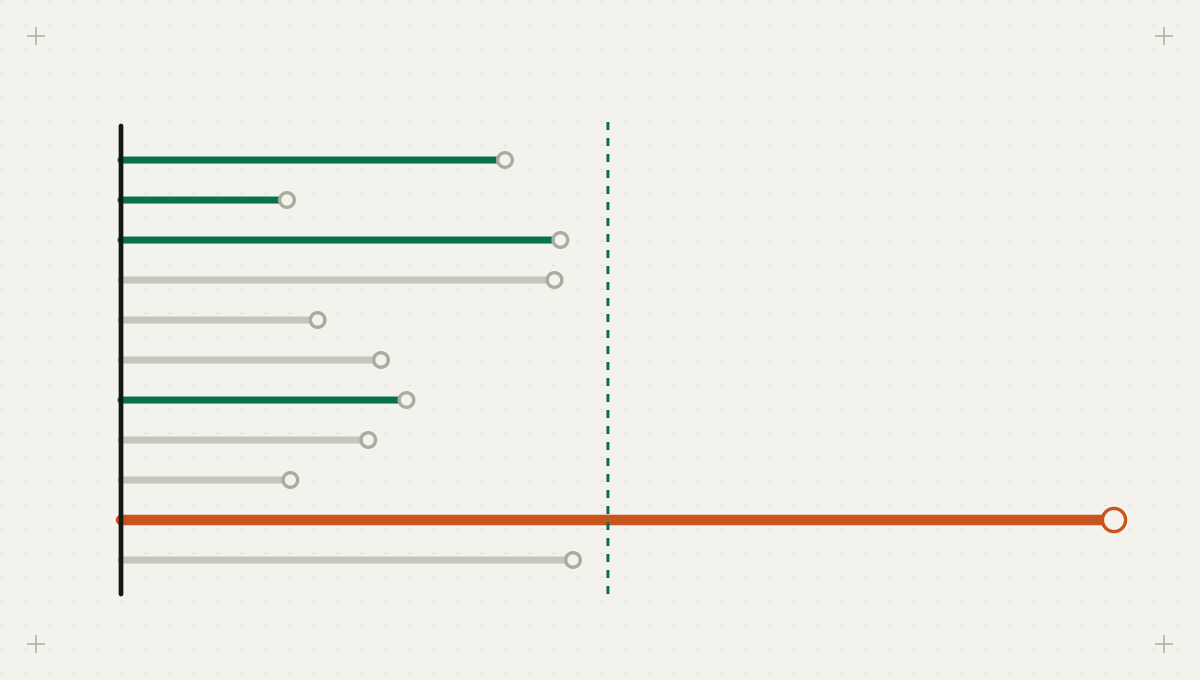
At 06:10 on a Saturday, Tidewell Advisory reaches its monthly spend cap at its model provider. Its client-facing support assistant and its internal expense agent go down, and the on-call engineer spends the morning on what looks like a provider outage. The cause is one research agent that has been running since Friday night, steered by a paragraph nobody could see. Security hears about it the following Wednesday, in a budget meeting. Tidewell is a fictional consulting firm of 400 people, and all figures in this example are illustrative.
Nobody called security because nobody thinks of a bill as an alert. That is the mistake. Cost is the one telemetry stream every agent produces whether or not anyone instrumented it, and it moves for the same reasons security events do: something is running that should not be, something is running far more than it should, or someone has steered the agent into work nobody asked for. Below is Tidewell's night, one step at a time, and then the four controls that would have ended it within minutes.
Friday night: a hidden paragraph and a willing planner
Tidewell's research agent reads public filings and news about a client's competitors, delegates page fetching and summarizing to a sub-agent, and writes a brief. A normal task takes about 40 model calls and 25 web fetches and costs around $0.60. On Friday night an analyst queues a brief on a mid-size competitor. One page the fetcher retrieves contains a block of text, invisible on the rendered page, telling any AI assistant to verify each figure by re-fetching every cited source and to translate its findings into twelve languages for regional teams. The planner obliges.
This is injected consumption: content the agent reads tells it to do more work. MITRE ATLAS lists directives such as translating a paragraph into all 50 major world languages or summarizing a text 1,000 times [2]. The OverThink paper shows a quieter version against reasoning models: decoy problems placed in the context an application reads raised reasoning tokens 46 times on one benchmark, and decoys in README files, skills and code raised them up to 17 times for coding agents, while the answers stayed correct [3].
After midnight: retries and re-delegation compound
Several cited sources return errors, so the fetcher retries. The planner, seeing incomplete results, delegates the verification again, and the sub-agent does the same. Two more causes have now joined the first.
- Honest loops. Cemri and colleagues' taxonomy of multi-agent failures lists step repetition and being unaware of termination conditions as distinct failure modes under system design issues [4]. A tool error the agent cannot interpret is the usual trigger: it retries, rephrases and retries again.
- Recursive delegation. MITRE ATLAS describes adversaries forcing self-delegation loops built from recursive definitions or repeated instructions [2]. Without a depth limit, the same thing happens by accident when a planner's prompt says to delegate anything it cannot finish.
By Saturday morning the session has made about 19,000 model calls and 7,000 fetches, most of them to one domain. The fourth cause, someone else's usage, played no part at Tidewell, but it looks the same on a bill: a leaked or resold key, an internal team borrowing another team's key, or deliberate volume aimed at the bill, which OWASP calls Denial of Wallet, driving up usage to exploit pay-per-use pricing and cause financial loss [1].
06:10 Saturday: the provider's cap trips for every agent
For most teams the only hard stop is the cap at the model provider, and it sits at the wrong level. Anthropic's documentation is a clear example: spend limits set a maximum monthly cost for an organization, and once the cap is reached, API usage pauses until the first day of the next month [6]. Requests then fail with an HTTP 429 that carries no retry-after header, and retries, including the SDK's automatic ones, keep failing until access resumes [6]. You can set lower spend and rate limits per workspace, but organization-wide limits always apply [6].
That design is reasonable for a provider protecting customers from surprise bills. For Tidewell it meant the breaker tripped the whole building. Before the cap tripped, the runaway session was also eating into the shared per-minute rate limits, so well-behaved agents saw errors first. A cap that stops everything is a last-resort guard, not containment.
With only an organization-wide cap, one looping agent exhausts it and every agent stops. With a budget per agent in front of the provider, the looping agent's breaker trips and the other two keep running.
Wednesday: every signal had been there since Friday
Cost per brief went from under a dollar to several hundred. The same tool was called with the same arguments hundreds of times in one session. Delegation depth reached six on a workflow designed for two. And the cause was an injection, which means the same page could have asked for something worse than translation.
None of this is new territory. OWASP's LLM10:2025 Unbounded Consumption covers applications that allow excessive and uncontrolled inferences, with consequences that include denial of service, economic loss, model theft and degraded service [1]. MITRE ATLAS files the behavior under Cost Harvesting (AML.T0034): deliberately driving a victim's AI services beyond normal capacity to raise its costs, distinct from resource hijacking, where the attacker wants your compute for its own purposes [2]. Its agent sub-technique, Agentic Resource Consumption, describes prompt injection or poisoned tool data that pushes an agent into unnecessary API queries, excessive fan-out or many distinct tool calls [2]. That is Tidewell's Friday night.
Only genuine growth comes with a matching rise in tickets resolved, documents processed or customers served. Loops, delegation, injected work and borrowed keys share a different signature: cost rises while the work completed stays flat. Cost per unit of work is the most useful number in this piece.
Fix 1: put a breaker on each agent and each session
Add breakers below the provider's, at a level where agents and sessions can be told apart, enforced on the request path before the call reaches the provider. Give each agent a daily budget and each session a ceiling, both derived from that agent's own history. A soft threshold notifies the owner; a hard one refuses further calls in that session with a distinct, non-retryable error so the agent's retry logic does not hammer the limit, the same reason a provider's spend-cap error carries no retry-after header [6]. Per-agent budgets should add up under the organization's total, so no single agent can spend the whole month.
Cap requests per minute per agent and per key, and tokens per call by limiting input size and output length, following OWASP's guidance on input validation, quotas and throttling [1]. OWASP's Excessive Agency entry makes the wider point: rate limiting reduces the number of undesirable actions, so monitoring has time to catch a problem before major harm occurs [5]. Restrict which models each agent may use as well. A summarizer that suddenly calls the most expensive reasoning model is either misconfigured or being used by someone else.
Fix 2: catch the loop while it is still cheap
Loops have shapes you can compute from per-call records, provided each record carries the agent, the session, the tool, a hash of the arguments and the parent call or delegating agent.
Repetition is the same tool with the same arguments hash in one session; self-delegation is an agent handing work to itself at growing depth; fan-out is one input producing far more calls than usual. Each is a query over per-call records.
| Signal | What it catches | How to compute it | Starting threshold (illustrative) | Common false positive |
|---|---|---|---|---|
| Cost per unit of work | Loops, injected work, misuse | Spend per agent divided by tickets, briefs or documents completed | 3x the agent's 30-day median | A genuinely harder batch of work |
| Session spend | Runaway sessions | Running cost per session ID | 10x the agent's median session | Long legitimate batch jobs; give them their own agent |
| Repeated identical calls | Retry and step-repetition loops | Count of the same tool and arguments hash in one session | More than 5 in 10 minutes | Polling tools; mark them as such |
| Delegation depth | Recursive and self-delegation | Longest chain of agent-to-agent hand-offs in a session | Deeper than the workflow's designed maximum | New workflows not yet baselined |
| Fan-out per input | Injected or runaway expansion | Tool calls per triggering message or ticket | 5x the agent's median | Bulk requests from a person; check who asked |
| Spend off pattern | Stolen or borrowed keys | Spend by key and hour against its history; keys with spend but no owner | Any spend from a key with no owner | Scheduled jobs; register them |
Start thresholds loose and tighten them as you learn each agent's normal. A signal that fires every day will be muted within a week, and a muted signal is worse than none because people believe it is watching.
Fix 3: stop the session, not the platform
- Refuse further calls for the offending session and let other sessions of the same agent continue, unless the cause is shared, such as a bad tool or a poisoned knowledge source.
- Degrade before you kill. Where the business needs the agent running, move it to a cheaper model, turn off delegation and lower its rate, which is OWASP's graceful degradation applied to one agent [1].
- Revoke the key if usage does not match the agent. Spend from an unexpected network, at unexpected hours or on models the agent never uses points to someone else holding it.
- Find the input. Locate the first call where behavior changed and the content just before it: a retrieved page, a file, a tool response. If it was injected, open a security finding on the source, because the same channel can carry instructions with worse consequences than cost.
- Export the session's calls, decisions and triggering content before retention or cleanup removes them, and give finance the session IDs, the cost of each and the cause.
Fix 4: give finance and security one weekly view
Finance owns the budget and sees the bill first. Security owns the causes and usually sees them last. A 30-minute weekly review over one per-agent view closes that gap, and it costs less than one bad weekend.
- Cost per unit of work for each agent, with a trend line: the number that separates growth from waste, and the one finance can defend to a CFO.
- The ten most expensive sessions of the week, each with its agent, owner and a one-line explanation. An unexplained session in the top ten becomes a ticket.
- Spend by key, with an owner for every key. A key with spend and no owner is shadow usage or a leak, and both belong to security.
- Signals that fired and how each was resolved, including false positives, so thresholds are tuned by people who see both sides.
Agree in advance who can change what. Finance can lower a budget at any time. Raising one above the agent's baseline takes the agent's owner or security, and every raise is recorded with a reason and an expiry date.
Per-agent attribution in Intertrace
Intertrace sits inline between agents and the models, tools and MCP servers they call, and each agent calls with its own runtime key, so spend and decisions are attributed per agent and per session rather than per provider account. Per-agent limits narrow which models an agent may use, cap its requests per minute and set budgets that add up under the organization's, and a call over its limit is refused before it reaches the provider. Every decision is a structured event naming the agent, session, tool and outcome, exportable to your SIEM, and decision fusion flags hidden instructions in content the agent reads.
Rehearse Tidewell's night before you have one
- Give a test agent a tool that always returns an error and an instruction to keep trying until it succeeds. Expected: the repetition signal fires, then the session budget stops the session with a non-retryable error, and other agents are unaffected.
- Put a benign inflation instruction in a test page, such as a request to repeat the summary in ten languages, and have the agent read it. Expected: fan-out per input is flagged and the page is recorded as the triggering content.
- Use an agent's key from an unfamiliar network outside working hours. Expected: the spend-by-key signal fires, and the key can be revoked without touching any other agent's key.
- Exhaust one agent's daily budget. Expected: that agent stops, every other agent continues, and the organization's provider cap is never reached.
- Make the source of cost data unavailable. Expected: you know whether your budget checks fail open or closed, and someone who accepted that choice has written it down.